What would this cost you?
Most voice-agent cost estimates compare vendors -- one TTS price against another, one LLM against another. This one compares architectures, holding the vendor stack fixed.
A naive build resends the whole growing conversation to the LLM on every turn and re-synthesises every reply from scratch, so its per-call cost climbs with call length. VARTA keeps a bounded, non-accumulating prompt per turn and replays cached audio for repeated phrasing instead of regenerating it, so a longer call does not automatically mean a proportionally more expensive one. Set your own call volume, call length, cache-hit rate and language below, pick a baseline stack to compare against, and see both totals -- and every line item behind them.
Indic India stack (naive build)
₹18,953 / month
VARTA, same stack's vendor rates
₹10,126 / month
Estimated difference: ₹8,827 a month (47% lower under VARTA's architecture).
Where the difference comes from
The total above is an assertion; this is the evidence — cost by component, monthly, under each architecture.
| Component | Indic India stack | VARTA |
|---|---|---|
| Text-to-speech | ₹43 | ₹19 |
| Language model | ₹97 | ₹5 |
| Speech-to-text | ₹18 | ₹23 |
| Telephony | ₹36 | ₹42 |
| Media platform | ₹32 | ₹32 |
This shows your own estimated monthly cost under two different architectures, built from public vendor list prices — never a VARTA rate card, and never a "from ₹X" price. VARTA carries no time-based unit rate, here or anywhere else: a rate that scaled with call duration would hide the effect of caching, which is exactly what this comparison exists to show.
Assumptions behind this estimate
- Exchange rate
- ₹84.00 = $1.00 (pinned figure, mirrored from the source cost model on 2026-08-27 — not independently re-checked against a live FX feed)
- Pace of a call
- About one agent-customer exchange every twenty seconds (6 conversation turns across a 60-second span of call time) — a pacing assumption, not a measurement of real call logs.
- Agent turn length
- ~120 characters of spoken reply — roughly one short sentence, the length of a typical confirmation or answer.
- Customer turn length
- ~15 tokens — a short reply such as a yes/no, a date, or a name.
Two modelling choices in this calculator make VARTA look cheaper than a real call may be, so the saving shown here is closer to a ceiling than a guarantee. First, we model VARTA’s context on each answered turn as a fixed 340-token prompt — the measured size of VARTA's own routing prompt, used as a lower bound, not a measurement of everything a live call's context can hold. Second, we charge exactly one LLM call for every turn VARTA has to think about, though a real turn can involve more than one call (for example, a classification step and a routing step). Neither assumption is applied to the other architecture, so both push the reported saving up, not down.
On the rates themselves: These figures are recorded as vendor list prices in the source cost model and have not been independently re-verified here — treat each as a starting point, not a confirmed-current rate. Each provider row is dated (asOf) to when it was last checked against its sourceUrl — some rows are older than others. List prices are used on purpose: a vendor offering a negotiated discount would only widen the savings gap this calculator shows, so this comparison is conservative rather than inflated. Refresh each rate against its source before citing it in a published case study.
Sources
- Indic India stack — text-to-speech vendor (checked 14 May 2026)
- Indic India stack — language model (checked 14 May 2026)
- Indic India stack — speech-to-text vendor (checked 15 Jul 2026)
- Indic India stack — telephony carrier (checked 14 May 2026)
- VARTA's speech-to-text vendor (fixed, not part of the compared stack) (checked 15 Jul 2026)
- VARTA's telephony carrier (fixed, not part of the compared stack) (checked 14 May 2026)
Where the saving comes from, on a real call
Both films use this calculator's own estimator: replaying repeated lines in the same voice, and answering most turns by rule before any model is asked.
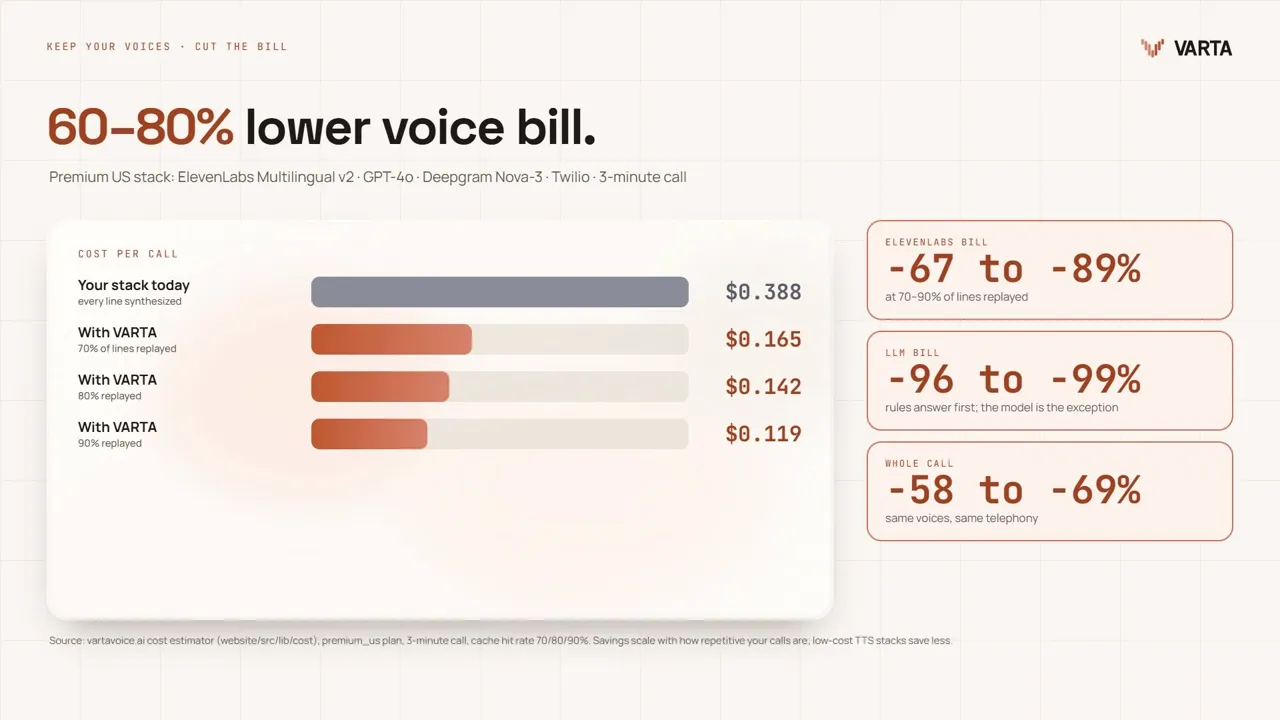
Premium voices · 1 min
Keep your voices. Cut the bill.
Keep the premium voice you chose. VARTA replays the lines an agent has said before from cache, in the same voice, and sends only the new ones to your provider.
Watch page and transcript · 1:06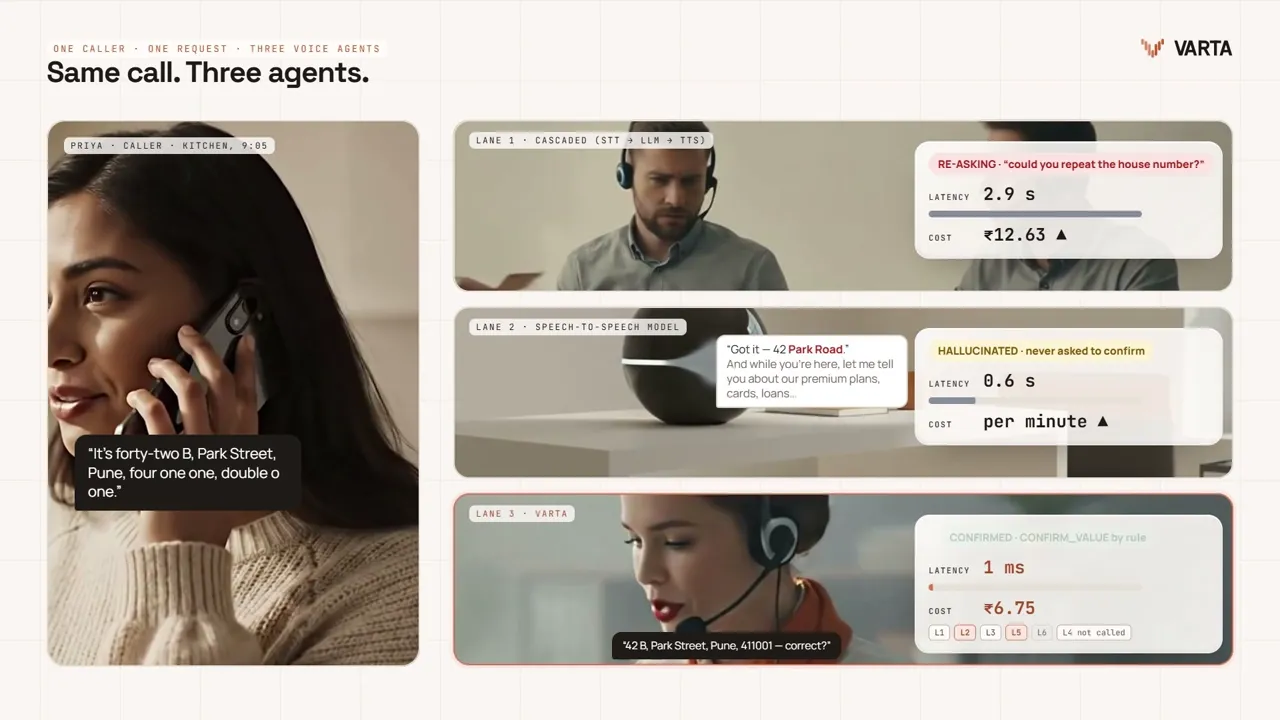
Head to head · 1 min
Same call. Three agents.
One caller, one request, three voice agents: a cascaded pipeline, a speech-to-speech model and VARTA. Watch which one waits, which one mishears the address, and which one confirms it by rule.
Watch page and transcript · 1:04Every figure above is built from public vendor list prices and the same per-unit rate tables and cost helpers that price real VARTA calls in production, run through a documented set of modelling assumptions and checked against goldens generated by that real code. Read exactly how it works -- including where this calculator's code stops being the same code that prices a live call, and the two assumptions that run in VARTA's favour -- on the methodology page.
Want this priced for your own workflows?
This estimate uses a generic call shape. Talk to us about a build sized to your actual call volume, languages, and existing telephony and vendor contracts.
Talk to sales