VARTA architecture
VARTA splits a voice agent into two halves. DAKSH does the slow, language-specific LLM work once, before any call, and writes it down as workflow data. The turn engine reads that data during the call with rules first and the LLM last, so most turns are answered in microseconds from pre-built audio.
Runtime · call time
VARTA Engine Architecture
How VARTA runs a live voice-agent call — a fixed cascade of rule-first layers with Hindi names, where the LLM is tried last and pre-built audio clips answer most turns.
AI Agent Training Center · design time
DAKSH Architecture
DAKSH is VARTA's AI Agent Training Center. How it turns an author's brief, pasted spec or one-line edit into a validated voice-agent workflow — steps, rules, language data and pre-built audio — so live calls need no LLM for any of it.
The architecture on film
How a sentence moves through the runtime, and how the two healing layers make the workflow cheaper and more correct with every call.
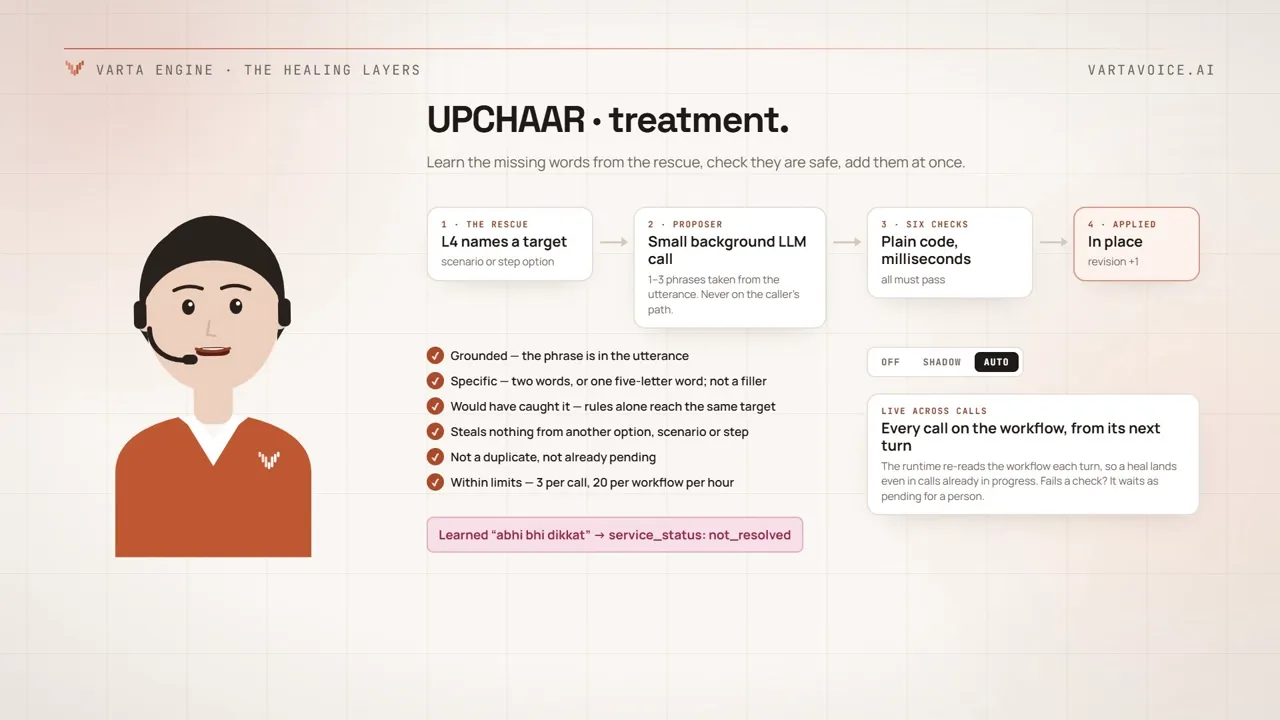
UPCHAAR and SHALYA · 2 min
How VARTA heals itself
Most voice agents stay as smart as the day they were written. VARTA’s two healing layers learn from every LLM rescue and propose structural fixes, checked before anything goes live.
Watch page and transcript · 2:02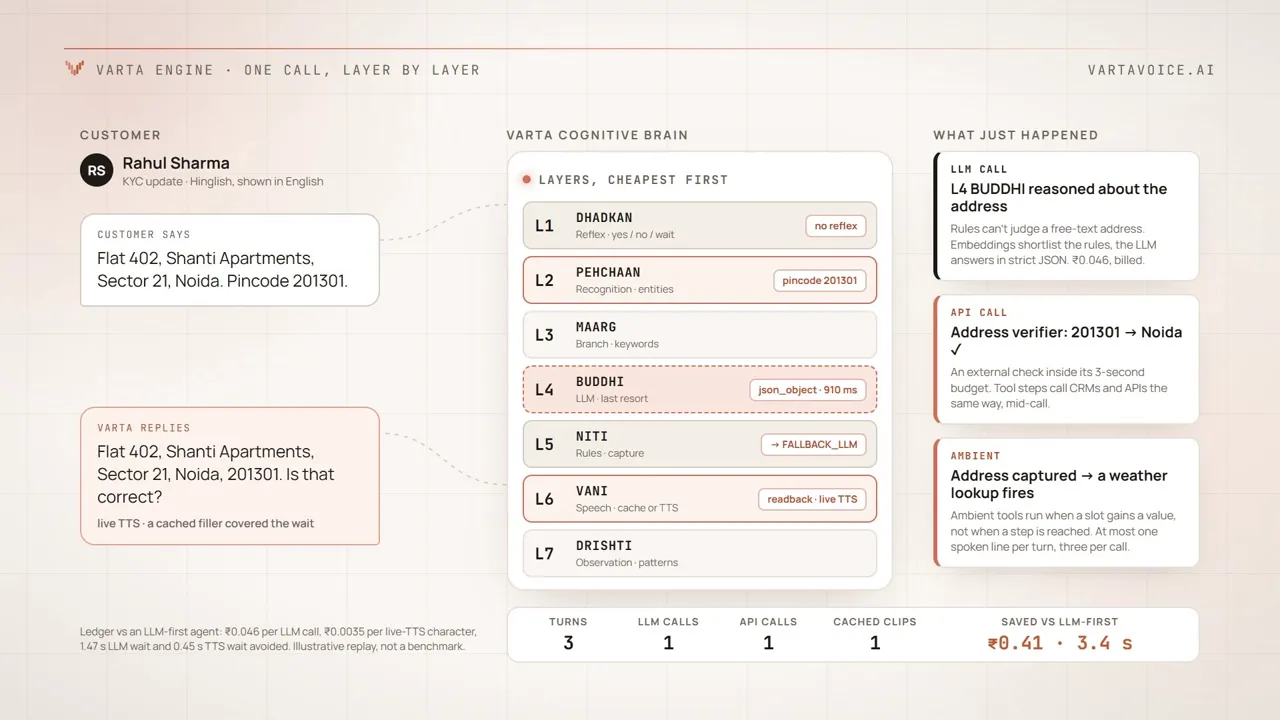
Inside the engine · 47 s
One sentence through the VARTA engine
Follow one caller sentence through VARTA layer by layer: reflex, recognition and rules first, an LLM only when nothing else can answer, every step on one visible ledger.
Watch page · 0:47